Auditing a Design System for MCP: Field Notes
The context
We are at a turning point for design and dev teams. With the arrival of the Figma MCP server, Claude Code and AI agents in daily workflows, the design system is no longer just a resource for humans. It becomes a source of truth that machines consume hundreds of times a day. That changes how we structure it and name things.
Recently on a client mission, I was asked to look at the existing design system through that lens. The goal was to see how to optimize it for an upcoming MCP (Model Context Protocol) deployment, so it could be used directly with Claude Code and smooth out the design and dev round trips.
I worked with the team's UI designer and honestly the work was already well underway. Components are named, the structure exists, things are documented. What I noticed is that the naming, which works very well day to day for the current team, could gain in consistency to scale better. That is pretty normal. Most DS I have seen evolve organically and at some point you need to take a step back to harmonize.
The underlying issue is simple: the small inconsistencies a human dev corrects instinctively become real problems the moment you plug an AI agent in, because the AI takes everything literally.
I'm sharing here what I observed and a few directions for improvement. These are not absolute truths. They are what worked in the contexts I have been involved in and what seems applicable broadly.
One principle that can serve as a thread for everything below: a developer who has never seen your tokens should be able to reasonably guess what a token does. If a name needs specific knowledge or a colleague to interpret, it is probably a good renaming candidate. The test also works for the AI: if a human discovering the DS struggles to guess the role of a token, the AI will have exactly the same problem.
What I observed and the directions for improvement
1. Reading direction of names can vary
This is probably the most common and the most understandable issue. When several people contribute to the DS over time, each one names with their own logic and individually it holds up. It just becomes a bit hard to scan at scale.
Names are easier to scan when they go from the broadest concept to the most specific. It also means alphabetically sorted lists naturally cluster related tokens together.
A direction that works well is to always go from broad to specific:
color.background.hover   rather than   hover.background.color
color.text.primary       rather than   primary.text.color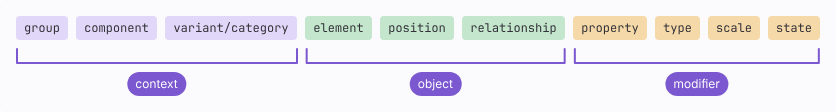
The naming convention enables you to choose a design token that matches your design intent. Design token names may include terms that define the context, object, and modifier for a design token. For example:
[group].[component].[variant/category].[element].[position].[relationship].[property].[type].[scale].[state]It looks innocuous, but on a list of 200+ tokens it really changes readability.
The MCP angle: when the AI calls get_tokens("color"), it receives the full list of color tokens. If the reading direction is consistent, all background tokens cluster together, all text tokens too. The AI identifies the right token in one read instead of scanning a disordered list.
2. A hierarchy between token tiers can help
Something I often see is that all tokens live on the same level. Raw values coexist with semantic tokens with no clear distinction. It works well when the team knows the system by heart, but it can become an issue when the AI or a new dev needs to find their way.
Most mature systems follow a three-tier model. It is a battle-tested approach worth adopting.
Tier 1: primitives (raw values)
Instead of using hex codes directly, colors are named with tonal values from 0 to 100 (or 100 to 1000). Each value expresses how much light is in the color.
color.blue.400
color.neutral.70
space.4
font.size.16
These tokens are the foundation. They are platform-agnostic and carry no semantic meaning. They are simply the catalogue of every available value.
Tier 2: semantic tokens (aliases)
This is where you give a value a role. An alias points to a primitive but states clearly what it is for:
color.text.primary       → color.neutral.10
color.background.danger  → color.red.500
color.border.default     → color.neutral.80
Aliases let you switch themes (dark mode, brand customization) by simply remapping values. The token name stays the same, the output adapts.
Tier 3: component tokens
Scoped to a specific component:
button.color.background.primary
button.color.background.primary.hover
input.color.border.error
They inherit from alias tokens but are scoped to the component context.
The MCP angle: without this hierarchy, when the AI calls get_tokens, it receives a flat list of 300 tokens and picks at random. With the three tiers it understands that color.text.primary is the right semantic choice for text, not color.neutral.10 which is just the raw value behind it. That is the difference between a generated component that makes sense and one that compiles but uses arbitrary values.
3. Add a notion of role to colors
This is a concrete case I lived during the mission. A blue-dark token was used as an alert background in one component and as an accent color in another. When the AI generated a new card component, it applied blue-dark on the background because the name carried no usage intent. The naming was not wrong, it just described the hue instead of the function.
Renaming it with a role logic made the issue disappear. The structure that often shows up in DS that scale well is: prefix-color-{role}-{modifier}-{theme}. The role defines the function (accent, border, text, status, surface). The modifier is optional and includes variations like weak, strong, active, hover, or success.
ds-color-accent
ds-color-border-strong
ds-color-text-weak
ds-color-status-success
The role first lets anyone immediately understand where it applies, without needing extra context.
The MCP angle: an AI looking for a color for an error state will naturally match ds-color-status-danger rather than guess that red-500 is "the color we use for errors here".
4. Harmonize size scales
I noticed that the different categories (spacings, radii, type) each used their own scale logic. That is fairly natural when categories are created at different moments by different people.
T-shirt sizes let anyone, technical or not, understand the differences and how they relate. Always use the short form (s, m, l, xl).
space-xs, space-s, space-m, space-l, space-xl
radius-s, radius-m, radius-l
font-size-s, font-size-m, font-size-l
Having the same logic everywhere reduces cognitive load, for humans and AI alike.
5. Think about a system prefix
It can sound secondary today but it becomes important with MCP. Token names that start with a prefix avoid collisions with other systems.
If the DS is called "Pulse" for example:
pulse-color-text-primary
pulse-space-m
pulse-font-size-l
The MCP angle: the AI will potentially manipulate tokens from different sources (your DS, a third-party lib, Tailwind tokens). The prefix lets it know immediately what comes from your system and what comes from elsewhere.
6. Lock a single casing
A small thing I noted: tokens with the same name but different capitalization are seen as unique tokens by the system. tokenName, tokenname and Tokenname will all be treated as different tokens.
Pick one format (kebab-case is the most common) and stick to it. It avoids silent bugs that are pretty annoying to debug.
7. A few technical pitfalls to keep in mind
Small things to anticipate to avoid surprises during code transformation:
When using dots as group separators, watch out for half-steps. Between spacing.1 and spacing.2, writing spacing.1.5 can cause problems because dev-side transformation tools may create name collisions.
Token names cannot start with the $ character, and curly braces should be avoided in names since they are reserved for token references.
Keeping the naming alive over time
Something I often see overlooked: naming is not a one-shot project you finish and forget. The real risk is drift at six months, when new components arrive and everyone falls back to their own habits.
A few things that work well to prevent that:
A clearly identified owner. Someone in the team (often the designer or front-end lead) who validates new token names before they are merged. It can be as simple as a check in the PR.
A one-page convention. Not a 20-page doc no one reads. Just the basic rules: reading direction, casing, prefix, color roles, size scale. If it does not fit on one A4, it is too complex.
A generator that protects curated sections. Token values and markup are extracted automatically from the source because if you write them by hand they drift. But descriptions, anti-patterns and high-level patterns are written manually because they represent intent and human judgment. The generator must always preserve those curated sections when it regenerates the rest. Otherwise someone runs npm run generate and all the editorial work disappears.
A periodic check. Every quarter or at each major release, you go back through the token list with the "new dev" test: would a stranger understand each name without help?
What it actually looks like on the MCP side
For those discovering the topic: the idea is to give the AI a queryable interface to the design system in real time, an MCP server it calls on demand whenever it needs the exact markup of a component or the right value of a token.
The goal is to eliminate invented class names, guessed markup and approximated token values, by letting the AI fetch the truth rather than guess it.
The server is intentionally thin: it loads pre-generated JSON at startup, formats responses and serves them. No database, no runtime parsing. The AI can call tools like get_component("modal") to retrieve the canonical markup with variants and anti-patterns, or get_tokens("color") to get the structured list of color tokens with their hierarchy.
Once that system is in place, iteration becomes extremely fast. Each iteration takes a few seconds. And the loop can even close in the other direction: Claude Code to Figma lets you capture a working UI and convert it into editable Figma frames, which creates a real design/code/design round trip without context loss.
For team-wide deployment, project-scoped servers store their config in a .mcp.json at the project root, designed to be versioned. Your devs all have the same tools right after git clone.
In summary
The investment is front-loaded but the benefit compounds over time: every component generated by the AI uses the right name, the right value and the right markup, without a manual review cycle to fix hallucinations.
In the vast majority of DS I have seen, the foundations are solid. It is often a matter of harmonizing and aligning naming, not a redesign at all. And moving to MCP is a good occasion to take that time, because the return on investment is concrete and measurable: fewer manual reviews, fewer post-generation fixes, and a language genuinely shared between designers, devs and now AI agents.
---
Related reading: for the bigger picture on why this matters, see AI-Personalized Adaptive Design, and on diagnosing the right problem before designing the system, Deep Systemic Design.
---
Sources & References
1. Louis Chenais, Design Tokens Book, the reference book on token architecture, tiers and naming conventions. designtokens.book
2. W3C Design Tokens Community Group, the official spec defining $type, $value and reserved characters in token names. w3.org/community/design-tokens
3. Nathan Curtis, Naming Tokens in Design Systems (EightShapes), foundational article on level-based naming and the broad-to-specific rule. medium.com/eightshapes-llc
4. Anthropic, Model Context Protocol, the official MCP specification. modelcontextprotocol.io
5. Figma, Dev Mode MCP Server, official documentation. help.figma.com
6. Brad Frost, Design Tokens FAQs, on the tier-1/2/3 token model. bradfrost.com